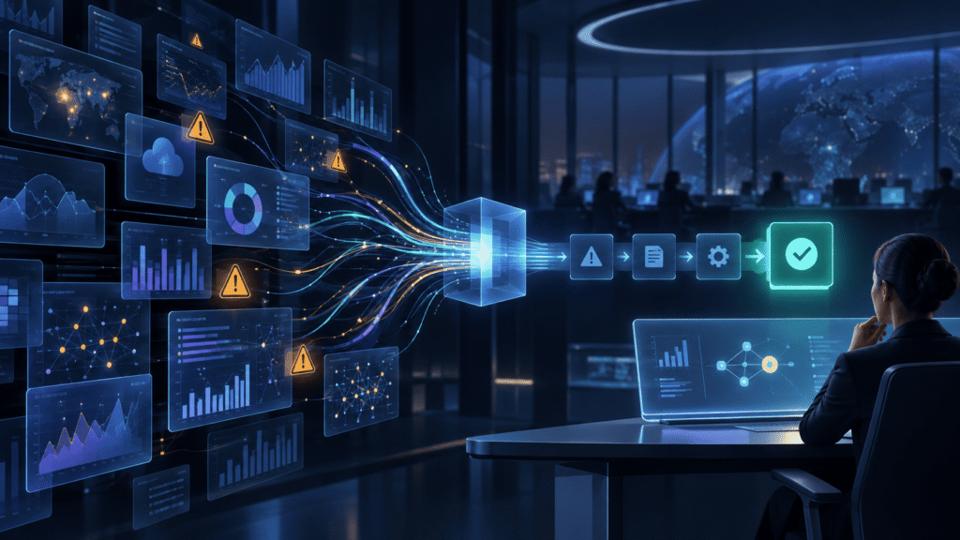
Modern IT teams have access to more data than ever. Dashboards track infrastructure health, application performance, user activity, security events, cloud costs, deployments, and service-level indicators. When something changes, there is usually a graph, alert, or status panel designed to show it.
That progress matters. Without visibility, teams are forced to troubleshoot through guesswork.
But visibility is only the beginning.
A dashboard can show that latency is increasing. It cannot always explain why, determine which customers are affected, choose the safest response, or confirm that the problem is truly resolved. Data becomes valuable when it helps people make better decisions at the right time.
The operational challenge many organizations face today is not a lack of information. It is the gap between information and action.
What IT visibility actually provides
IT visibility is the ability to see relevant signals across systems, services, infrastructure, and users. It can include metrics, logs, traces, events, tickets, configuration changes, deployment records, and business-impact indicators.
Good visibility helps teams answer questions such as:
- Is a system healthy?
- What changed recently?
- Which component is generating errors?
- Are performance levels within expected limits?
- Where are capacity, security, or reliability risks emerging?
These answers create an essential operational baseline. They help teams detect unusual behavior and investigate issues with more evidence.
The limitation is that a visible signal is not automatically a meaningful insight. A high CPU graph, a red alert, or a failed health check may be important, or it may be a symptom, a duplicate, or a normal response to a temporary condition.
The dashboard paradox
As organizations add more tools, they often create more dashboards. Each one solves a local visibility problem, but the overall operating experience can become more fragmented.
An engineer may need to move between monitoring, cloud, deployment, security, ticketing, and communication tools to understand one incident. Every dashboard presents a slice of reality, often with its own terminology, thresholds, and time windows.
This creates a paradox: the organization can see more individual signals while understanding the complete situation less clearly.
The result may be:
- Alert fatigue from duplicated or low-value notifications
- Longer investigations because context is spread across tools
- Confusion about which metric represents the actual customer impact
- Delayed escalation while teams compare competing signals
- Manual updates between monitoring, ticketing, and collaboration systems
More screens do not necessarily create more clarity.
Visibility is not the same as understanding
The difference between visibility and understanding is context.
Suppose an application begins returning errors after a deployment. A dashboard may display the error rate, response time, and deployment event. Understanding requires connecting those signals and asking whether the deployment is a likely cause, which service path is affected, whether the issue is spreading, and what rollback or mitigation options are available.
That reasoning often depends on information outside the dashboard itself:
- Recent changes and approvals
- Service dependencies
- Similar incidents from the past
- Runbooks and known workarounds
- Ownership and escalation policies
- Customer or business impact
- Risk associated with each possible response
IT observability improves the collection and correlation of signals, but teams still need an operating layer that turns those signals into a clear recommendation or next step.
The four steps from data to action
Strong operational intelligence connects four stages:
1. See
Collect reliable signals from the systems that matter. This includes technical telemetry and, where possible, indicators of user and business impact.
2. Understand
Correlate events, identify patterns, and distinguish likely causes from symptoms. The goal is to create a coherent view of the situation rather than a pile of alerts.
3. Decide
Prioritize the issue, evaluate available responses, and select the next action based on impact, confidence, risk, and policy.
4. Act and learn
Execute the approved response, record the result, and use the outcome to improve future detection and decision-making.
Many dashboard programs are strong at the first step and partially address the second. The greatest opportunity is improving the third and fourth.
Why decision-making is harder than detection
Detection is often binary: a threshold was crossed, a check failed, or a pattern looks unusual. Decision-making is more nuanced.
A team may need to determine whether an event is urgent, whether it represents a real incident, and whether an automated response could make the situation worse. It may need to balance speed against change risk or service recovery against data integrity.
That is why the same alert can require different responses in different contexts. A brief spike during a planned release is not equivalent to the same spike during a critical customer workflow.
Effective IT decision-making therefore needs more than fast data. It needs shared context, clear ownership, and an agreed operating model.
How AI can help move beyond dashboards
AI does not make dashboards unnecessary. It can make the information inside them easier to interpret and use.
An AI-assisted operations layer can help teams:
- Summarize the current state across multiple systems
- Group related alerts into a probable incident
- Identify changes that preceded an issue
- Retrieve relevant runbooks and prior incident notes
- Estimate likely impact and affected dependencies
- Recommend investigation or remediation steps
- Draft a ticket, incident update, or stakeholder message
- Execute low-risk actions within defined guardrails
The value is not simply conversational access to data. The value is reducing the effort required to move from scattered evidence to a defensible next step.
Human oversight remains essential for high-impact actions. The system should make its evidence, assumptions, confidence, and recommended action visible so that operators can validate the decision rather than blindly accept it.
Design dashboards around decisions
One practical improvement is to design operational views around decisions instead of data sources.
Rather than asking, “What can this tool display?” ask:
- What decision does the team need to make?
- Which signals are required to make it?
- How quickly must the decision be made?
- What would change the recommended response?
- What action can follow from the decision?
For example, an incident response view should not only display error rates. It should bring together the probable service impact, recent changes, affected dependencies, current owner, relevant runbook, and safe response options.
This turns a dashboard from a passive display into a decision workspace.
Measure outcomes, not dashboard activity
Dashboard usage is a weak measure of operational maturity. A team can spend more time looking at dashboards without improving reliability or response quality.
More useful measures include:
- Time from detection to useful diagnosis
- Time from diagnosis to approved action
- Percentage of alerts that lead to meaningful work
- Number of duplicate or correlated alerts per incident
- Time spent collecting context manually
- Percentage of incidents with documented contributing factors
- Recurrence rate after remediation
- Accuracy of impact and priority classification
These measures connect visibility to operational outcomes. They also reveal where better automation, integration, or process design can create the most value.
A practical path from dashboards to decisions
Organizations can make progress without replacing every monitoring tool. A staged approach is often more effective.
Start with one high-value workflow
Choose a recurring process such as incident triage, change-risk review, or service-request routing. The workflow should have a clear owner and a measurable outcome.
Map the evidence needed for action
Document which signals, records, and systems people consult before deciding what to do. This exposes context gaps and unnecessary handoffs.
Add correlation and summarization
Bring related signals into one operational view and produce a concise explanation of what appears to be happening. Preserve links to the original evidence.
Introduce recommendations before autonomy
Start by recommending the next step rather than executing it. This lets teams evaluate quality, build trust, and improve the underlying workflow.
Automate bounded actions
Once a recommendation is reliable, automate reversible, low-risk actions with permission controls, logging, and rollback paths.
Learn from results
Capture whether the action worked, what changed afterward, and whether the same issue recurred. Feed that learning back into detection and response design.
What this means for EBlissAI
The next opportunity in IT operations is not another isolated dashboard. It is an intelligence layer that helps teams understand signals in context and move confidently toward action.
For EBlissAI, this means helping organizations connect visibility with prioritization, decision support, and carefully governed automation . The goal is to make operational data useful at the moment a team needs to decide what happens next.
If your organization has invested in monitoring but still spends too much time interpreting alerts and coordinating responses, consider reaching out to EBlissAI to explore the gap between what your systems show and how your teams act.
Conclusion
Visibility is foundational, but it is not the finish line. Dashboards show signals; effective operations turn those signals into understanding, decisions, and measurable outcomes.
The shift from dashboards to decisions requires better context, stronger correlation, clearer ownership, and carefully governed automation. AI can help accelerate that shift by organizing evidence, recommending next steps, and handling bounded actions.
The question for modern IT teams is no longer only, “Can we see what is happening?” It is also, “Can we understand its significance and act before the cost grows?”
Frequently asked questions
What is IT visibility?
IT visibility is the ability to see relevant signals across infrastructure, applications, services, users, and operational processes. It helps teams detect changes and investigate technical conditions.
Why is IT visibility alone not enough?
Visibility shows what may be happening, but it does not automatically provide context, determine business impact, prioritize the issue, or select the safest response. Teams need an additional layer for interpretation and action.
What is the difference between IT visibility and IT observability?
IT visibility focuses on seeing signals across an environment. IT observability goes further by using those signals to understand internal system conditions and investigate why a result occurred. In practice, both support better operational decisions.
How can AI improve dashboard-driven operations?
AI can correlate related alerts, summarize system state, connect events to recent changes, retrieve relevant operational knowledge, recommend next steps, and automate low-risk actions within defined guardrails.
How should a company move from dashboards to decisions?
Start with one high-value workflow, identify the evidence needed for its decisions, add correlation and summaries, introduce recommendations, and then automate bounded actions after quality and safety have been validated.